Senior Data Engineer

Joaquín Soro Castelló

Data & backend engineer based in Brno. I build APIs, backend services and data pipelines with Go, Python, Kafka, PostgreSQL, AWS and Kubernetes.

About me

I'm a data and backend engineer. Since 2022 I've worked at an AI startup, two consultancies, a payments company and Deutsche Telekom, on data pipelines, backend services and data platforms.


I currently work at Deutsche Telekom on AI forecasting for fibre (FTTH) rollout, where I led the adoption of Palantir Foundry. I care most about clean, well-tested backend code, especially hexagonal architecture and high test coverage. Day to day I work with AI coding agents like Claude Code, using spec-driven development with OpenSpec.


English: fluent (C1) · Spanish: native

Experience

Senior Data Engineer (AI)
Deutsche Telekom Services Europe
Jul 2025 - Present · hybrid (Brno)

• Working in the Guided Reporting team within Predictive Analytics (AI Shared Services), delivering custom AI, analytics and forecasting solutions for Telekom • Led Palantir Foundry adoption, learning it from scratch and building successful products with it • Built the FTTH rolling forecast tool: several highly time-consuming Excel processes turned into an automated workflow with optional AI forecasting, used by 500+ people • Designed the ontology (data model); built and maintained incremental pipelines and backend codebases • Collaborated on frontend tasks and other projects • Onboarded, mentored and supported junior developers • Technologies: Python, Palantir Foundry, Dagster, PostgreSQL, Docker, Kubernetes

Data Engineer / Go Software Engineer (Payments domain)
Epos Now · Data & Insights team
Mar 2024 - Jun 2025 · remote

• Mainly worked on merchant reporting tools in the Epos Now product • Built a transactions reporting API on AWS in Go, plus other new Go services; refactored legacy C# services • Set the standard for hexagonal architecture in Go across the reporting backend services • Built pipelines for reporting, monitoring and integrations • Debugged and maintained legacy SQL Server stored procedures behind existing reports • Built a proof of concept for orchestrating the legacy ETL pipelines with Airflow • Technologies: Go, C#, AWS, PostgreSQL, SQL Server, Kafka, Airflow, Docker, Kubernetes

Data Engineer / Python & Scala Engineer (Airlines domain)
NEXT Digital · consultancy, client: Iberia (IAG)
Jun 2023 - Mar 2024 · remote

• Worked in the real-time operations data engineering team for Iberia (International Airlines Group) • Migrated legacy processes and infrastructure to Kafka and ksqlDB on AWS, and built Scala Spark Streaming jobs and Airflow pipelines • Built backend API services following hexagonal architecture and SOLID principles • Contributed to projects on baggage, weight and fuel calculations, route connections and trip planning • Technologies: Kafka, ksqlDB, Spark, Airflow, PostgreSQL, Python, Scala, Docker, Kubernetes

Data Engineer (ELK) / Python Engineer (Banking domain)
Accenture · consultancy, client: CaixaBank
Dec 2022 - Jun 2023 · remote

• Worked on a Data Governance platform (an in-house, Airflow-like PaaS for scheduling and running data jobs) for CaixaBank Tech's Enterprise Architecture project • Built microservice-based data processing for total cost of ownership (TCO) calculations: job definition and scheduling, data ingests, and exports to dashboards, visualizations and documents • Developed internal tools for ELK administration tasks and data migrations • Technologies: Python, Elasticsearch, Kibana, Docker, Kubernetes

Junior Software Engineer (AI SEO startup, SaaS)
Smartbrand (sb.digital)
Jul 2022 - Dec 2022

• Worked on DWX, Smartbrand's AI SEO startup (SaaS, automated internal link optimization) • Built features for the platform on microservices in GCP, and helped move it from the initial MVP to a cloud-native, distributed, workflow-based architecture • Wrote the initial Helm charts in collaboration with an external infrastructure engineer • With senior guidance, forked and revived the open-source Scrapy Cluster project for distributed web scraping, feeding the ML pipeline that restructured customers' internal links • Researched technologies such as Elasticsearch and Airflow, and built proofs of concept and reports for new workflows and use cases • Technologies: Python, Kafka, Redis, ELK, Kubernetes, Helm, GCP, MongoDB, Scrapy

Software Engineer Intern (AI SEO startup, SaaS)
Smartbrand (sb.digital)
Mar 2022 - Jun 2022

• Worked across several microservice repositories, adding unit tests and BDD tests (Gherkin), and preparing them for a future move to the cloud as the MVP grew • Documented services and API endpoints • Built small features and supported team members with delegated tasks • Produced reports and assessments, and took part in technical discussions • Internship completed as part of my vocational degree's workplace training • Technologies: Python, Java, RabbitMQ, Git, Docker, Linux, MongoDB

Education

Bachelor's Degree in Computer Engineering (paused)
Universitat Oberta de Catalunya
2022 - 2024

Part-time, Computing and AI branch.

Higher Technical Degree in Multi-platform Application Development
IES Poeta Paco Mollá
2020 - 2022 · >2000h

Official vocational degree focused on backend development.

Web Design & Development Bootcamp (Vue3, TypeScript)
Escuela de Organización Industrial (EOI)
2022

Samsung Innovation Campus: AI & Deep Learning
Universidad de Málaga
2021

Projects

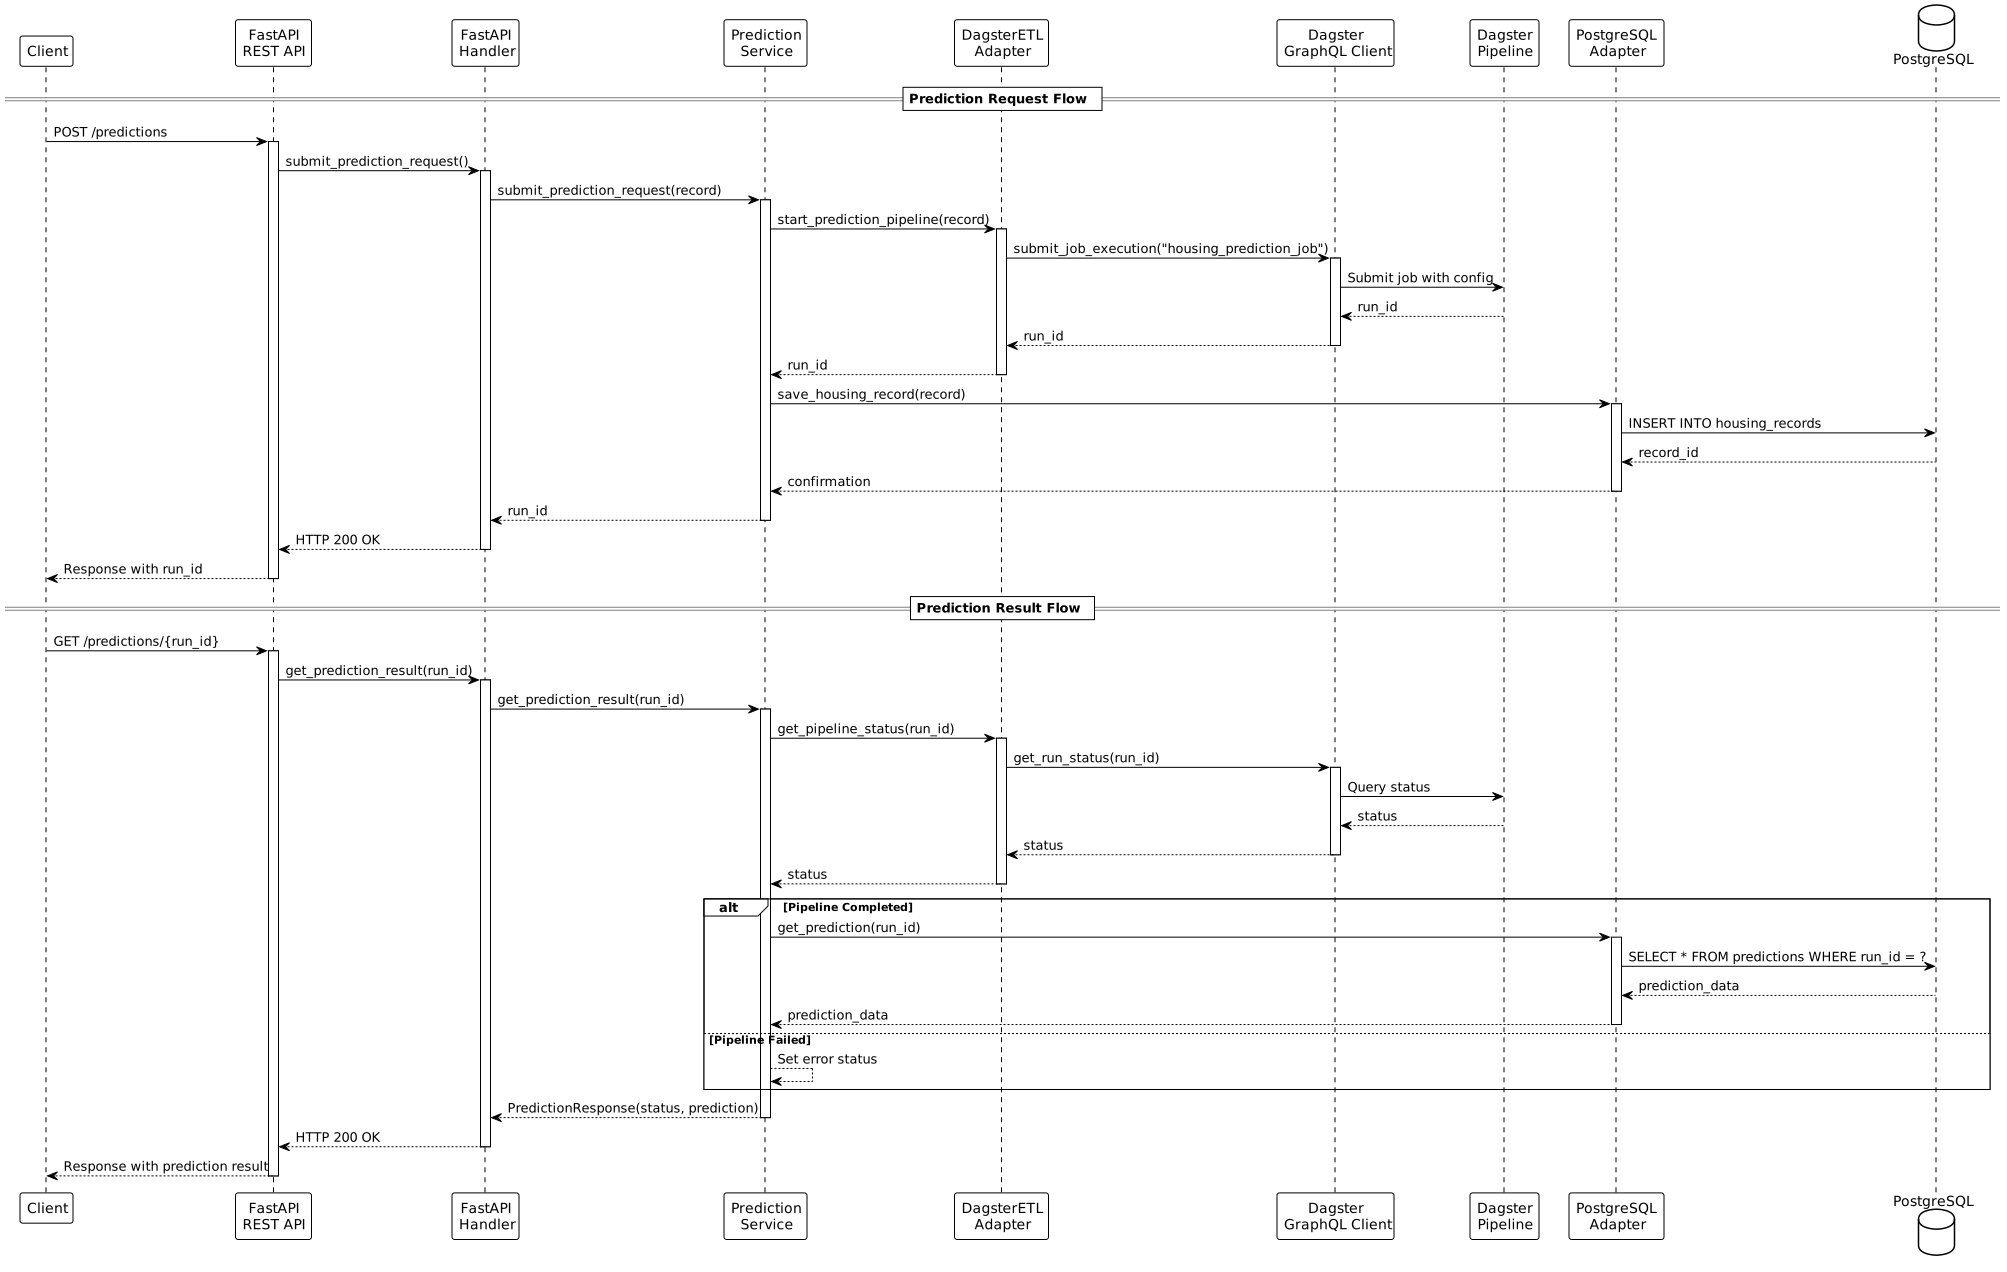
Sequence diagram of the prediction request and result flows

Housing price prediction service

A FastAPI service that runs predictions through a Dagster pipeline and stores the results in PostgreSQL. Built with hexagonal architecture, 48 unit and integration tests, Prometheus and Grafana monitoring, and Docker Compose deployment.

  • Python
  • FastAPI
  • Dagster
  • PostgreSQL
  • scikit-learn
  • Prometheus
  • Grafana
  • Docker
Hexagonal architecture diagram of the pipeline

PokeAPI → DuckDB pipeline

An Extract & Load pipeline that pulls related PokeAPI entities into a layered DuckDB warehouse (raw capture and typed staging), with HTTP caching and a star-schema design for the transform step. Built with hexagonal architecture, 35 tests, mypy and ruff, and specs written with OpenSpec.

  • Python
  • DuckDB
  • httpx
  • OpenSpec
  • uv

FastAPI + MLflow

A FastAPI service for training models and serving predictions, using MLflow for experiment tracking and the model registry, MongoDB for metadata, and Docker Compose.

  • Python
  • FastAPI
  • MLflow
  • MongoDB
  • Docker

Get in touch

Send me a message or email me at contact@jsoro.dev.